Technical Insights into Chunking for Maximizing RAG Accuracy: Optimal Solutions for Leveraging Internal Documents
“We built an internal policy bot, but the answers are irrelevant and useless.” — This common challenge faced by many IT departments is often not due to a lack of LLM (Large Language Model) performance, but rather the method of “data segmentation” (chunking). A chunking strategy that optimizes vast internal documents into sizes easily searchable by AI is the most critical process determining the accuracy of RAG (Retrieval-Augmented Generation). Based on real-world implementation examples, this article explains practical technical insights to drastically reduce the burden on IT departments.
1. Why "Fixed-Length Chunking" Fails to Reduce Inquiries
A common pitfall in initial RAG implementation is adopting "fixed-length chunking," which mechanically splits data based solely on character count. For instance, if data is split every 300 characters, critical regulatory text may be cut off mid-sentence, preventing the AI from correctly understanding the context. In our consulting experience, we have seen many cases where this "contextual fragmentation" leads to hallucinations (plausible-sounding falsehoods), resulting in the counterproductive outcome of users having to call the IT department for verification anyway.
As shown in the figure above, accuracy improves dramatically simply by refining the chunking method. A common practice in the field is ensuring that heading information, such as "Article X," is retained within each chunk. This clarifies which section the answer is citing, thereby building user trust.
2. Implementing "Semantic Chunking" to Maintain Hierarchical Structure
Internal regulations and manuals have a hierarchical structure consisting of major, medium, and minor categories. Even if you vectorize them while ignoring this structure, the search hit rate will not improve. In our Own EC Site Construction and Growth Support projects, we recommend "structured splitting" using HTML and Markdown tags to enhance the searchability of product manuals.
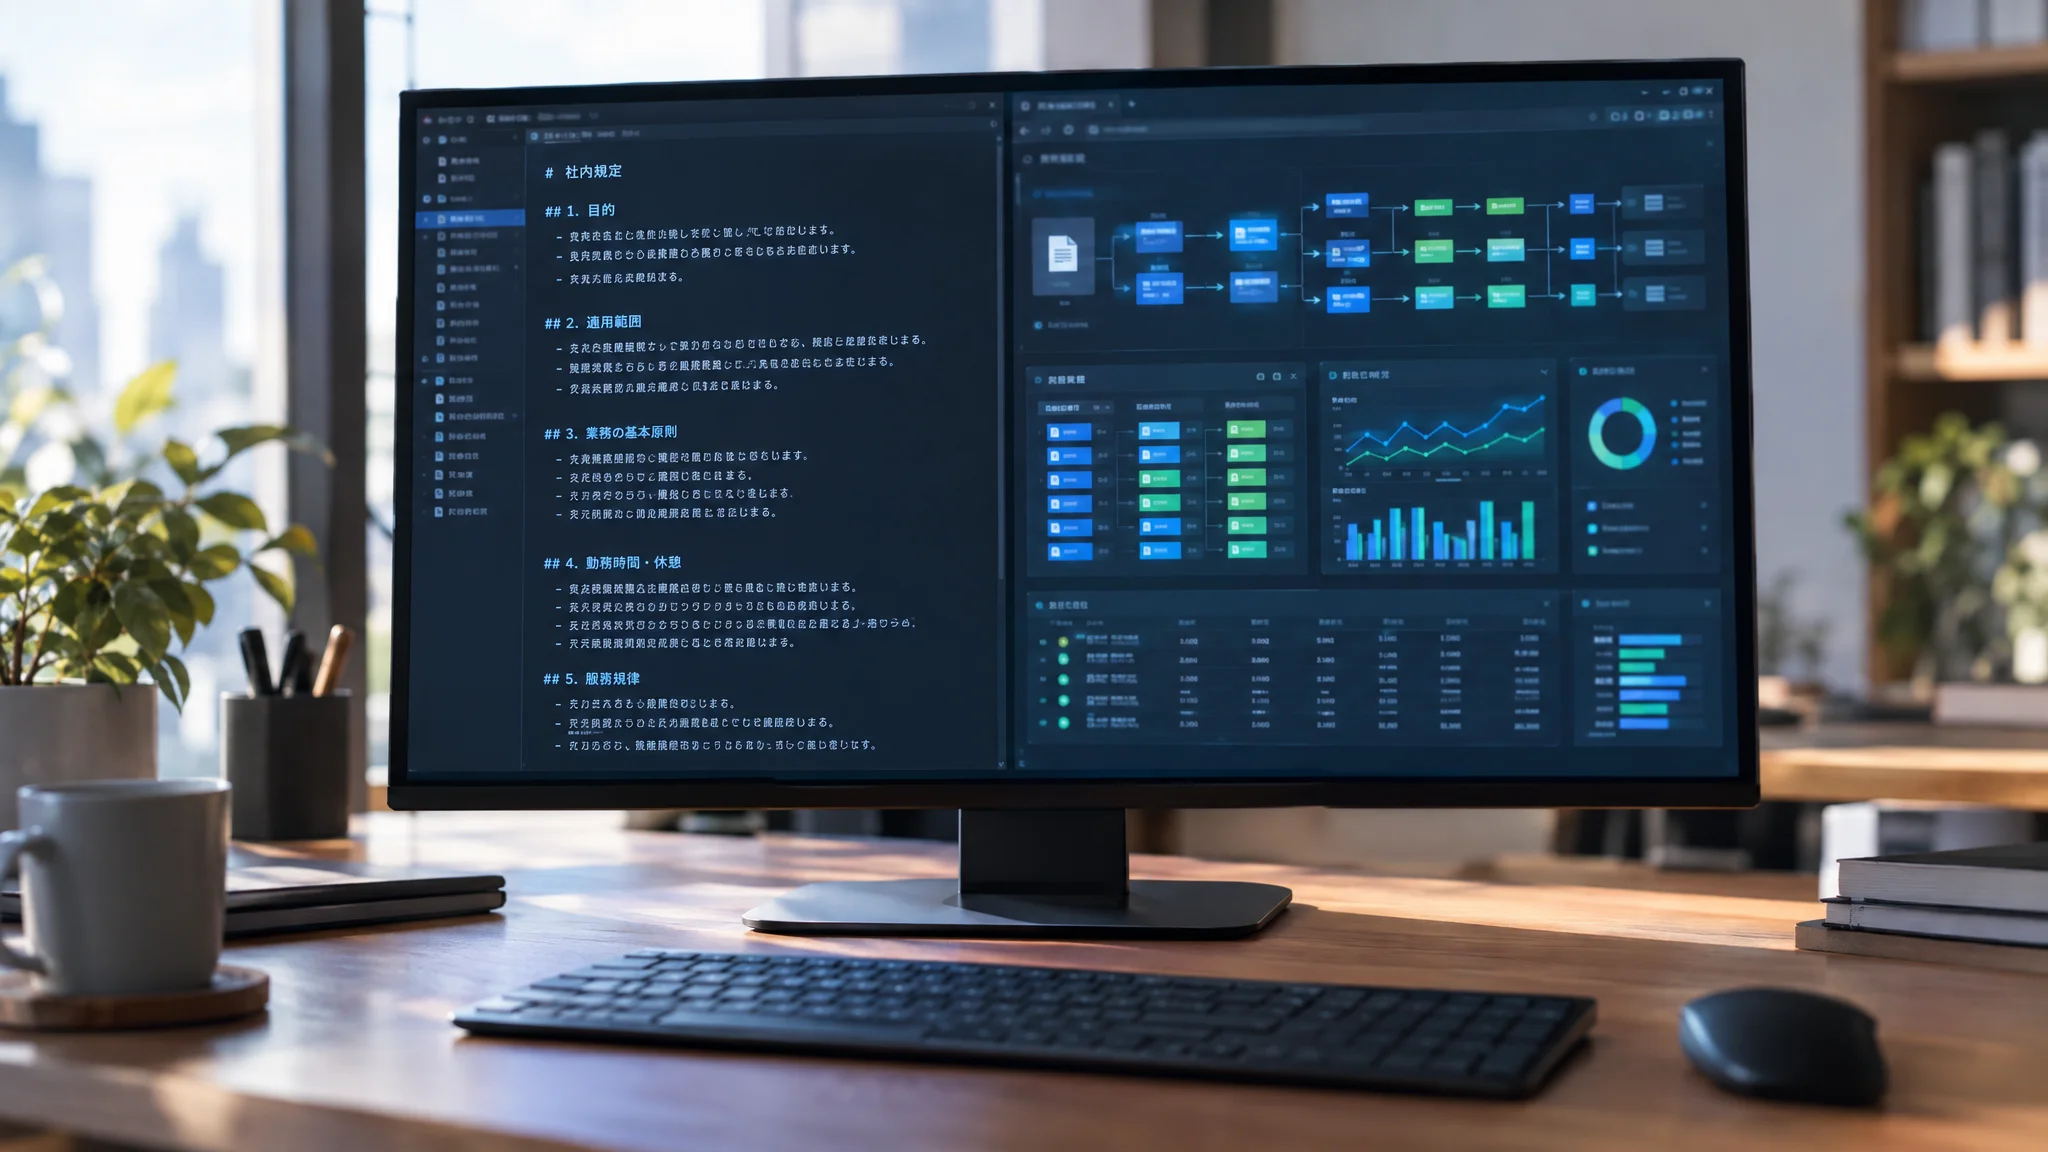
具体的には、再帰的文字分割(RecursiveCharacterTextSplitter)を用いつつ、セパレーターとして「\n\n」「\n」「。」「、」の優先順位を定義します。これにより、意味のまとまりを維持したまま、埋め込みモデルのトークン制限内に収めることが可能になります。支援現場では、この設定を1ミリ単位で調整するような泥臭い作業こそが、最終的な「問い合わせ削減」という成果に直結すると確信しています。
3. Automating Metadata Tagging to Reduce IT Department Man-hours by 80%
For high-precision RAG, "metadata (attribute information)" for each chunk is essential. By attaching information such as "Is this a 2024 regulation?" or "Which department is this document for?", you can narrow the search scope and maximize accuracy. However, doing this manually places a massive burden on IT departments.
This is where "self-metadata tagging"—using the LLM itself to automatically generate metadata—becomes effective. When inputting chunks, the AI extracts summaries and keywords, which are then stored in the vector database payload. In our actual support projects, we have seen cases where this automation reduced data maintenance man-hours by approximately 80%. To free IT departments from a "storm of inquiries," the perspective of "leveraging AI to build AI" is essential.
FAQ
- Q. What is the appropriate chunk size?
- A. Generally, 512 to 1,024 tokens are recommended, but for Japanese, the standard approach is to begin testing with around 300 to 600 characters. When context is a priority, setting a 10% to 20% 'overlap' to partially duplicate adjacent chunks is a fundamental rule of thumb in practice.
- Q. Why are the tables in my PDF not being read correctly?
- A. Since PDF tables are prone to structural issues, we recommend converting them to Markdown format before chunking. For complex tables, the most stable method is to treat the entire table as a single chunk and attach a summary of its content as metadata.
- Q. If there is an existing FAQ, how should it be divided?
- A. Since each FAQ unit (one question, one answer) already constitutes a complete meaning, it is best to treat a single Q&A as one chunk rather than forcing a split. In this case, designing the system to use the question text as the vectorization key and the answer text as the context will improve the search hit rate.
Freeing your IT department from the "storm of inquiries"
From improving RAG accuracy to optimizing internal data. Our consultants with hands-on experience will partner with you.
Talk to us for a free strategy consultationSummary
Chunking, which holds the key to RAG accuracy, is not just a technical task but the very "reconstruction" of internal knowledge. By understanding the limitations of fixed-length chunking and implementing semantic chunking that reflects document structure and context, AI can finally evolve into a "useful partner." To reduce the burden on IT departments and boost company-wide productivity, we recommend starting by reviewing how your existing data is segmented.
Published: October 9, 2024 / By: Osamu Yasuda
Osamu Yasuda
Senior Managing Director & COO
Meets Consulting Inc.
Supported 100+ EC operations & logistics projects; specialist in operations and cost optimization
Related Articles
References
- [1] Lewis, P., et al. (2020). Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks.
- [2] OpenAI. (2024). Best practices for retrieval-augmented generation.